We may earn a commission if you buy through links on this page. It never changes a score or a ranking. How we make money
The bottom line
Useful open-model infrastructure, but check model pricing, capacity terms and portability before committing.
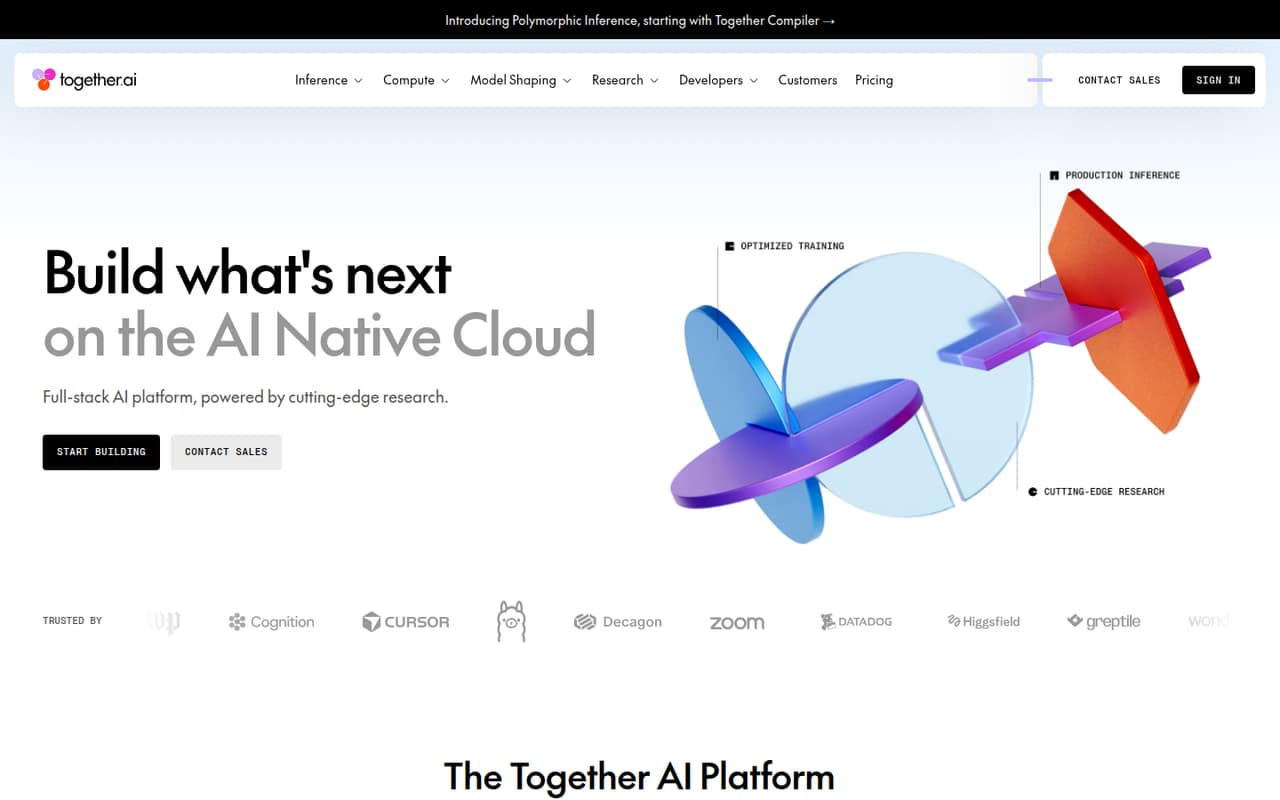
Together AI is a hosted AI platform that combines model inference APIs with batch processing, reserved capacity, GPU compute, fine-tuning and storage. It is aimed at teams that want to build on open models without operating every part of the serving stack themselves.
Usage-based pricing can be inexpensive for some models, while output tokens, reserved capacity and dedicated GPUs change the bill quickly. Reddit users praise speed and throughput, but also report concerns about price and billing disputes.
Good fit if
- Teams serving open models
- Batch inference workloads
- Teams needing GPU capacity
Skip it if
- Teams requiring full self-hosting
- Projects needing fixed monthly costs
- Buyers needing published SDK guarantees
ScoresHow it rates
What works
- Serverless inference avoids managing serving infrastructure
- Batch API supports up to 30 billion tokens per model
- Provisioned Throughput includes a 99% uptime SLA
- GPU compute, fine-tuning and storage sit on one platform
- Some listed models have zero-dollar token prices
What doesn't
- Token costs vary by model and input or output
- Some GPU and container prices require a sales quote
- Free-tier allowances are not published
- Together's platform license and self-hosting path are unclear
- Reddit users report billing and price concerns
01What Together AI is, technically
Together AI is a hosted AI infrastructure platform, not a model library or a self-hosted inference server. Its main integration surface is model inference through APIs. The platform also offers batch inference, reserved token capacity, dedicated model and container deployments, GPU clusters, managed storage, and managed fine-tuning.
In a typical stack, an application sends inference work to Together AI rather than provisioning and operating its own serving fleet. Serverless Inference is for on-demand model calls; Batch Inference handles asynchronous workloads of up to 30 billion tokens per model. Provisioned Throughput reserves inference capacity and includes a 99% uptime SLA. GPU compute and model-shaping tools extend the platform into training and infrastructure work.
The service is aimed at teams building with open models that want managed infrastructure, from experimentation to production. That can reduce operational work, but it also puts serving availability, capacity terms and part of the application’s model interface under a hosted provider.
02Together AI API, SDKs and docs
The core integration is API-based inference. Together AI describes Serverless Inference as high-performance inference APIs and says Provisioned Throughput has drop-in API compatibility for production workloads. Batch Inference provides an asynchronous path for large jobs. Together Link is presented as a way to run open models inside a harness you already use, but the homepage does not identify specific harnesses or protocols.
The developer resources include technical documentation, cookbooks, demos, a model library, a playground and Together Chat. Those are useful starting points for selecting models and working through implementation patterns. The homepage does not name programming languages, SDK packages or a CLI. Confirm SDK and language support in the vendor’s documentation before choosing a client library; do not assume that drop-in API compatibility means every SDK or feature behaves identically.
For production integration, check request formats, streaming behavior, error handling, model availability and rate limits in the docs. The platform lists serverless, batch and reserved-capacity options, so the right interface depends on whether the workload is interactive, asynchronous or capacity-sensitive.
03Together AI pricing for developers
Together AI has a free plan, and its model library includes free offerings such as Ternary Bonsai 27B at $0 per 1M input and output tokens. The vendor does not publish the free plan’s allowance. Serverless Inference is usage-based: Kimi K3 is listed at $3 per 1M input tokens and $15 per 1M output tokens; Tev1 4B Experimental is $0.04 per 1M input tokens with free output. Batch Inference lists Kimi K3 at the same rates and Ternary Bonsai 27B at $0.
Provisioned Throughput is billed per PTU per minute, with fixed inference capacity and a 99% uptime SLA; the estimator assumes about 43,800 minutes monthly. Dedicated Inference lists HGX H100 at $5.49 per GPU-hour and HGX B200 at $8.99. HGX H200, B300 and GB200 NVL72, plus reserved rates, require a quote. Dedicated Container Inference uses custom pricing. Media generation adds separate charges, including $0.0154 per FLUX.2 dev image and $0.115 per ByteDance Seedance 2.5 video. Settings can change image costs.
04Together AI: open source, self-hosting and lock-in
Together AI provides access to open-source models, but that does not make the hosted platform itself open source. Model licenses vary, so check the terms for each model before shipping it. The vendor does not publish a platform source license, a self-hosted Together server option or a defined data-export path.
The service is presented as managed infrastructure, including hosted inference and dedicated deployments. Teams can reduce model-level lock-in by keeping application logic behind an internal model adapter and choosing models whose weights and licenses support another serving stack. That does not remove migration work: request formats, model behavior, fine-tuning artifacts and provisioned-capacity arrangements may differ elsewhere.
Before committing, ask how to retrieve prompts, outputs, fine-tuned weights and stored data, and what happens to reserved capacity if you leave. For a hard self-hosting requirement, evaluate the model and serving software separately from Together AI’s hosted services.
05Together AI in production
The platform offers several ways to scale: serverless inference, batch workloads up to 30 billion tokens per model, Provisioned Throughput with a 99% uptime SLA, and dedicated GPU infrastructure. The stated SLA applies to Provisioned Throughput; confirm the contract, exclusions and remedies before treating it as an application-level availability guarantee. The pricing page does not give general rate limits, so ask about model-specific quotas, burst behavior and how limits change with capacity.
Reddit reports are mixed. One commenter says Together is “very fast” and can handle many tokens, while another says it can be “not necessarily inexpensive.” A separate thread includes a user reporting a collections email over a $0.51 balance after using a credit. These are individual accounts, not service guarantees, but they make billing controls and account support worth checking.
For production, set usage alerts, validate fallback behavior and test the exact models and deployment type your application will use. Ask the vendor about data handling, security controls, compliance coverage and incident escalation before sending sensitive workloads.
From the threadsWhat users say
Reddit sentiment is mixed: users describe fast inference and useful throughput, while others question cost or report a billing dispute. These comments are individual experiences, not a consistent measure of service quality.
together.ai is very fast
not necessarily inexpensive
It’s cheap and fast and I can push a lot of tokens through
now I’m getting emails saying I owe $0.51 from COLLECTIONS
Questions people ask
What does Together AI actually do?
Together AI provides hosted infrastructure for building with AI models. Its services include serverless and batch inference, provisioned throughput, dedicated model deployments, GPU compute, fine-tuning and managed storage. Developers can use it to serve open models without operating the entire inference stack themselves.
Is Together AI free to use?
Together AI lists a free plan and some free model options. Ternary Bonsai 27B is listed at $0 per 1M input and output tokens, and Tev1 4B Experimental has free output tokens. The vendor does not publish the free plan’s allowance, so check account limits before relying on it.
Does Together AI offer an uptime SLA?
Together AI lists a 99% uptime SLA for Provisioned Throughput. The stated SLA is tied to that capacity option, not necessarily every service or serverless model. Review the service terms for exclusions, measurement details and remedies before using it as an availability commitment.
Can I run Together AI models on my own infrastructure?
Together AI’s services are presented as managed infrastructure, and the vendor does not publish a self-hosted Together server option. Some models are open source, but licensing and weight availability vary by model. Check each model’s terms and evaluate a separate serving stack if self-hosting is required.
How much does Together AI cost?
Pricing depends on the model and service. Kimi K3 is listed at $3 per 1M input tokens and $15 per 1M output tokens. Dedicated Inference lists HGX H100 at $5.49 per GPU-hour and HGX B200 at $8.99. Reserved capacity and some GPUs require a quote.