We may earn a commission if you buy through links on this page. It never changes a score or a ranking. How we make money
The bottom line
A fast inference API with OpenAI compatibility; production cost and limits need vendor confirmation.
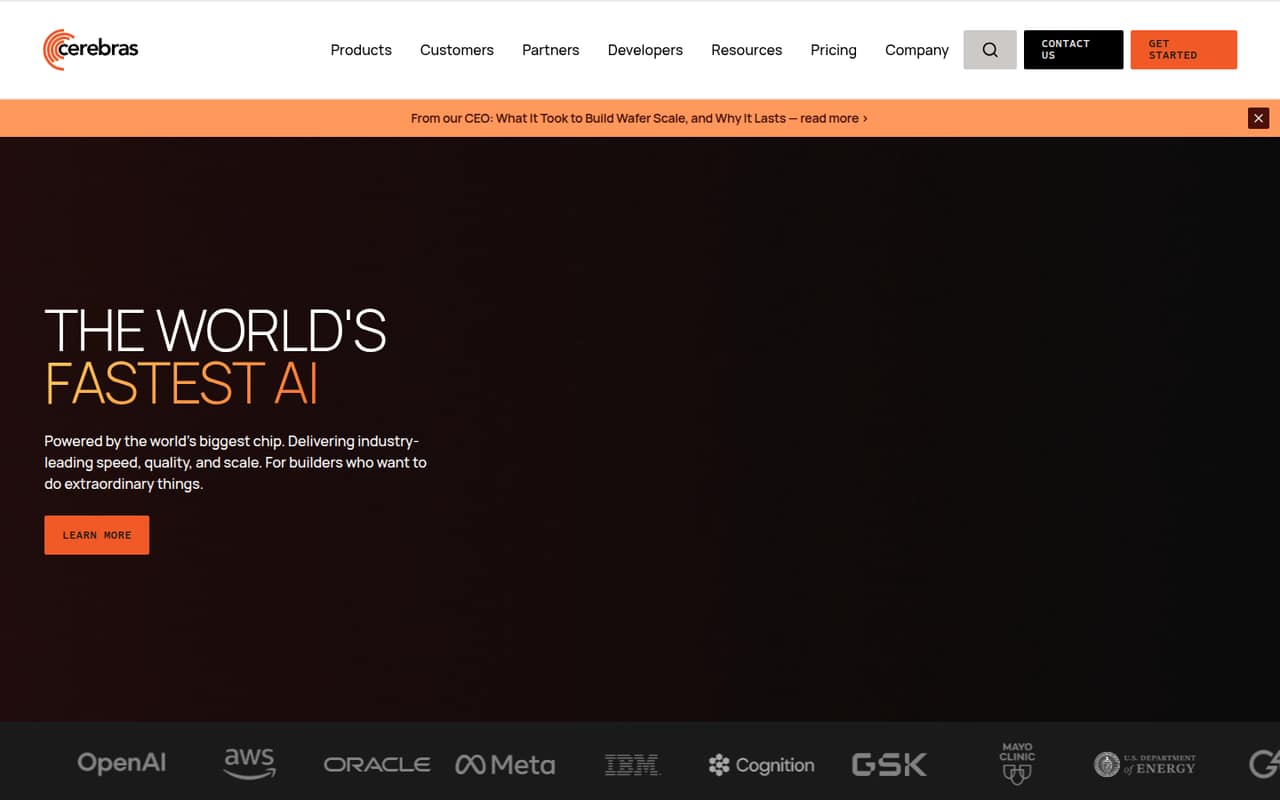
Cerebras Inference is a hosted model-serving API on Cerebras hardware, with cloud, dedicated and on-prem deployment options. OpenAI API compatibility and an API-key endpoint give teams a familiar integration path, while in-region serving supports latency and data-residency needs.
Developer pricing is pay-as-you-go by token, but production capacity is custom-priced and the Developer plan is not intended for production. We’d validate model availability, rate limits, SDK support and deployment terms before putting it on a production path.
Good fit if
- Teams prioritizing low-latency inference
- OpenAI API-compatible integrations
- Workloads needing in-region deployment
Skip it if
- Teams needing published production pricing
- Buyers requiring confirmed SDK coverage
- Projects seeking a free production tier
ScoresHow it rates
What works
- Drop-in OpenAI API compatibility
- Public endpoint for regularly updated open models
- Cloud, dedicated and on-prem options
- In-region inference for residency requirements
- Fine-tuning and pre-training options
What doesn't
- Developer plan is not intended for production
- Enterprise pricing is custom
- Rate-limit values are not published
- SDK and language support needs confirmation
- Source availability and data export terms need confirmation
01What Cerebras Inference is, technically
Cerebras Inference is a hosted model-serving API that runs models on Cerebras hardware. It sits behind an application or agent that sends inference requests, receives model output, and handles its own product logic, storage and user-facing features. The public endpoint serves a regularly updated lineup of open models; cloud, dedicated and on-prem options cover different deployment needs.
The problem it targets is serving model responses quickly at production scale. Cerebras says inference runs in-region to support latency, data-residency and compliance requirements. Its homepage also describes training, fine-tuning and serving on one platform. OpenAI API compatibility is the main integration bridge for teams with existing clients, though model behavior and availability still depend on the selected model and deployment. The vendor cautions that observed speed varies by workload, configuration, date and model, so treat headline performance claims as workload-specific rather than a service-level guarantee.
02Cerebras Inference API, SDKs and docs
The homepage describes a public endpoint accessed with an API key and drop-in OpenAI API compatibility. That gives developers an API integration surface, but the published product details do not name a particular SDK, programming language, CLI, webhook or plugin. Confirm current SDK support, endpoint details, authentication requirements and request formats in Cerebras’ developer docs before choosing a client library.
The compatibility claim may reduce changes for an application already built around OpenAI-style requests, but it does not establish identical model names, response behavior or feature coverage. Check which models are available for the public endpoint and which require an applicable deployment. The homepage says the open-model lineup is regularly updated, so pin model availability in deployment planning rather than assuming a model remains available indefinitely. For an existing codebase, validate its API client against the chosen model and ask Cerebras about migration support and versioning.
03Cerebras Inference pricing for developers
The Developer plan is pay-as-you-go per token and is intended for development, evaluation and experimentation, not production. The listed GPT OSS 120B rates are $0.35 per 1M input tokens and $0.75 per 1M output tokens. Qwen 3.8 27B is $0.99 per 1M input tokens and $1.49 per 1M output tokens. A one-time $5 promotional credit is available with a valid payment method and expires after 30 days; there is no free plan.
Your bill grows with input and output token use. The pricing page does not list monthly or annual subscription prices, and there is no published starting price for Enterprise. Enterprise is custom-priced for production-ready capacity, priority and higher rate limits, enhanced latency options, and access to supported models for applicable deployments. PayGo credit prices are not published. Customized model weights, fine-tuning and training are available by agreement, with prices not published. Ask for a quote that specifies model, capacity, rate limits and any training work.
04Cerebras Inference: open source, self-hosting and lock-in
Cerebras offers cloud, dedicated and on-prem deployment options, so the service is not limited to a shared hosted endpoint. The product details do not identify a license for the inference platform or say that its serving software is open source. The listed open models are not evidence that the platform itself is open source.
The vendor does not publish data-export terms in the published product details. Ask how to retrieve prompts, outputs, logs and any fine-tuned weights, and what support is available when ending a deployment. OpenAI API compatibility can make the application-side interface more familiar, but model-specific behavior, hardware and deployment configuration can still create migration work. Before adopting it, test an alternative provider or model path and confirm what artifacts can move with you.
05Cerebras Inference in production
Cerebras positions the service for production-scale serving and lists Enterprise capacity, higher rate limits and enhanced latency options. It does not publish numeric rate limits, uptime commitments or detailed service-level terms here. Ask for those limits, incident response commitments, scaling behavior and model availability terms before setting production targets. The vendor says inference runs in-region, but teams with compliance obligations should confirm the regions, controls and contractual terms they need.
The vendor cautions that observed inference speed varies with workload, configuration, date and models tested. Benchmark claims therefore need validation against your own prompts, concurrency and latency targets. A Reddit thread announces Cerebras Inference coming to Gimlet Cloud, but it does not report operational experience or reliability. We found no user-reported production evidence in that discussion to weigh against the vendor’s claims. Treat the service as a candidate to qualify, not as a proven fit for your workload.
From the threadsWhat users say
The Reddit discussion is an announcement and invitation to comment, not a set of user reports about the service. It provides too little evidence to judge developer satisfaction or production experience.
Cerebras inference is coming to Gimlet Cloud
Announced by Cerebras on X
What would you like to see from us next?
Reply here or join us on Discord:
Questions people ask
Does Cerebras Inference work with the OpenAI API?
Cerebras describes its offering as drop-in OpenAI API compatible and says developers can access the public endpoint with an API key. Confirm the current endpoint, supported request formats, model names and feature coverage in Cerebras’ developer docs before switching an existing client.
Can I use Cerebras Inference on-prem?
Yes. Cerebras lists cloud, dedicated and on-prem deployment options. Confirm which models and features are supported for the specific deployment, along with regional availability, capacity, service terms and pricing, before planning a production rollout.
Is Cerebras Inference free?
There is no free plan. The Developer plan is pay-as-you-go, and Cerebras lists a one-time $5 promotional credit for a valid payment method. The credit expires after 30 days and the Developer plan is not intended for production use.
What rate limits does Cerebras Inference have?
The product details do not publish numeric rate limits. Cerebras lists higher rate limits and best priority for Enterprise, but does not give the values. Ask the vendor for limits by model and deployment, plus how they change with capacity and what happens when requests exceed them.
Can I fine-tune models with Cerebras Inference?
Cerebras says the platform supports fine-tuning and pre-training with your own data. Customized model weights, fine-tuning and training are listed as services by agreement, with prices not published. Ask which models and deployments support your training use case and what happens to your data and weights.